The challenge
Where teams get stuck
The problems we're most often brought in to solve.
- 01
Fluent answers that are wrong
An LLM feature produces articulate but inaccurate responses, with no way to verify them against source material.
- 02
Data exposure concerns
Legal and security teams are cautious about sending customer or internal data to external model providers.
- 03
Unpredictable cost to serve
Token consumption grows with adoption, and no one can forecast what the capability will cost at full scale.
- 04
No objective quality measure
Prompt changes are judged on a few examples, so an improvement in one area quietly degrades another.
Overview
Generative AI & LLM Engineering at VulcanTech
Generative AI development is the engineering of applications that use large language models to answer, summarise, extract and draft from an organisation's own knowledge. VulcanTech builds assistants that answer from your documents, copilots embedded in your products and LLM features for core workflows. Our scope spans model selection, retrieval architecture, prompt and output design, evaluation and deployment, with disciplined attention to accuracy, data privacy and cost to serve.
Key deliverables
- Use-case assessment and model benchmark
- Production LLM application or capability
- Retrieval pipeline and knowledge index
- Evaluation suite with baseline results
- Usage, cost and quality monitoring
What you get
What Generative AI & LLM Engineering includes
Model selection and benchmarking
Hosted and open-weight models compared on your own tasks for quality, latency and cost before selection.
Retrieval-augmented generation
Answers grounded in your documents and data, with citations so users can verify every source.
Prompt and output engineering
Versioned prompts, structured outputs and validation make LLM responses consistent enough to build products on.
Evaluation pipelines
Automated test sets and scoring run on every change to track accuracy, safety and regressions.
Privacy and safety controls
PII redaction, content filtering, access controls and private deployment options for sensitive data.
Cost and latency optimisation
Caching, streaming, model routing and batching keep responses fast and spend within budget.
Capabilities
Specialised Generative AI & LLM Engineering services
- Foundation Model Integration & Fine-TuningFoundation models embedded in your products and operations, adapted to your domain where the evidence supports it.Learn more
- Enterprise Knowledge & Retrieval (RAG)Institutional knowledge made instantly accessible, with every answer traceable to its source.Learn more
- Conversational AI & CopilotsCustomer-facing assistants and in-product copilots that resolve requests accurately and escalate with context.Learn more
Our process
How we deliver
A delivery process you can see into — from first workshop to production support.
- 01
Discovery
A focused working session on your objectives, constraints and existing systems. It concludes with a scoped proposal and a clear view of value, risk and effort.
- 02
Architecture & planning
We agree the target architecture, data model and integration approach before product code is written, and secure your sign-off.
- 03
Iterative delivery
Working software reaches a staging environment on a regular cadence, giving stakeholders continuous visibility and the ability to steer priorities.
- 04
Assurance & hardening
Automated testing, accessibility and performance budgets, and a security review are completed before anything reaches production.
- 05
Launch & continuity
We manage cutover and remain engaged through an agreed support period, with a structured handover to your teams or ongoing operation by ours.
Engagement models
Work with us the way that suits you
Outcome-based delivery
A defined scope, timeline and commercial model agreed after discovery. We own delivery risk against the agreed outcomes.
Best for: Well-defined initiatives, MVPs and first releases
Dedicated product teams
A cross-functional pod — engineering, design, QA and delivery leadership — aligned to your roadmap and scaled as priorities change.
Best for: Long-term product development and evolving roadmaps
Team extension
Senior engineers embed in your organisation, work inside your processes and report to your leaders — on contracts that assign all IP to you.
Best for: Adding specialist capability without growing headcount
Tools & technologies
The stack we build with
- OpenAI API
- Claude API
- Google Gemini
- Llama
- LangChain
- LlamaIndex
- pgvector
- Azure OpenAI
- AWS Bedrock
- Python
- OpenAI API
- Claude API
- Hugging Face Transformers
- PyTorch
- vLLM
- LiteLLM
- Python
- LlamaIndex
- LangChain
- pgvector
- Elasticsearch
- Qdrant
- OpenAI API
- Claude API
- Python
- OpenAI API
- Claude API
- Vercel AI SDK
- Next.js
- Node.js
- Zendesk API
- Twilio
Why VulcanTech
A partner, not a vendor
Senior engineering, honest delivery, and work we can name.
Senior engineers own delivery
The engineers who scope your programme in discovery are the engineers who deliver it. There is no hand-off to a junior bench after contract signature.
Engagement models that fit
Outcome-based delivery, dedicated product teams, team extension or global capability centres, matched to how your organisation prefers to work.
A verifiable track record
Every customer story we publish describes real production work, naming the client wherever confidentiality allows, including public-sector platforms secured through competitive tenders.
80+ projects in 16 countries
Delivered since 2021 across the public sector, real estate, healthcare, manufacturing and consumer technology, for regulated and high-growth organisations alike.
Customer stories
Proven delivery
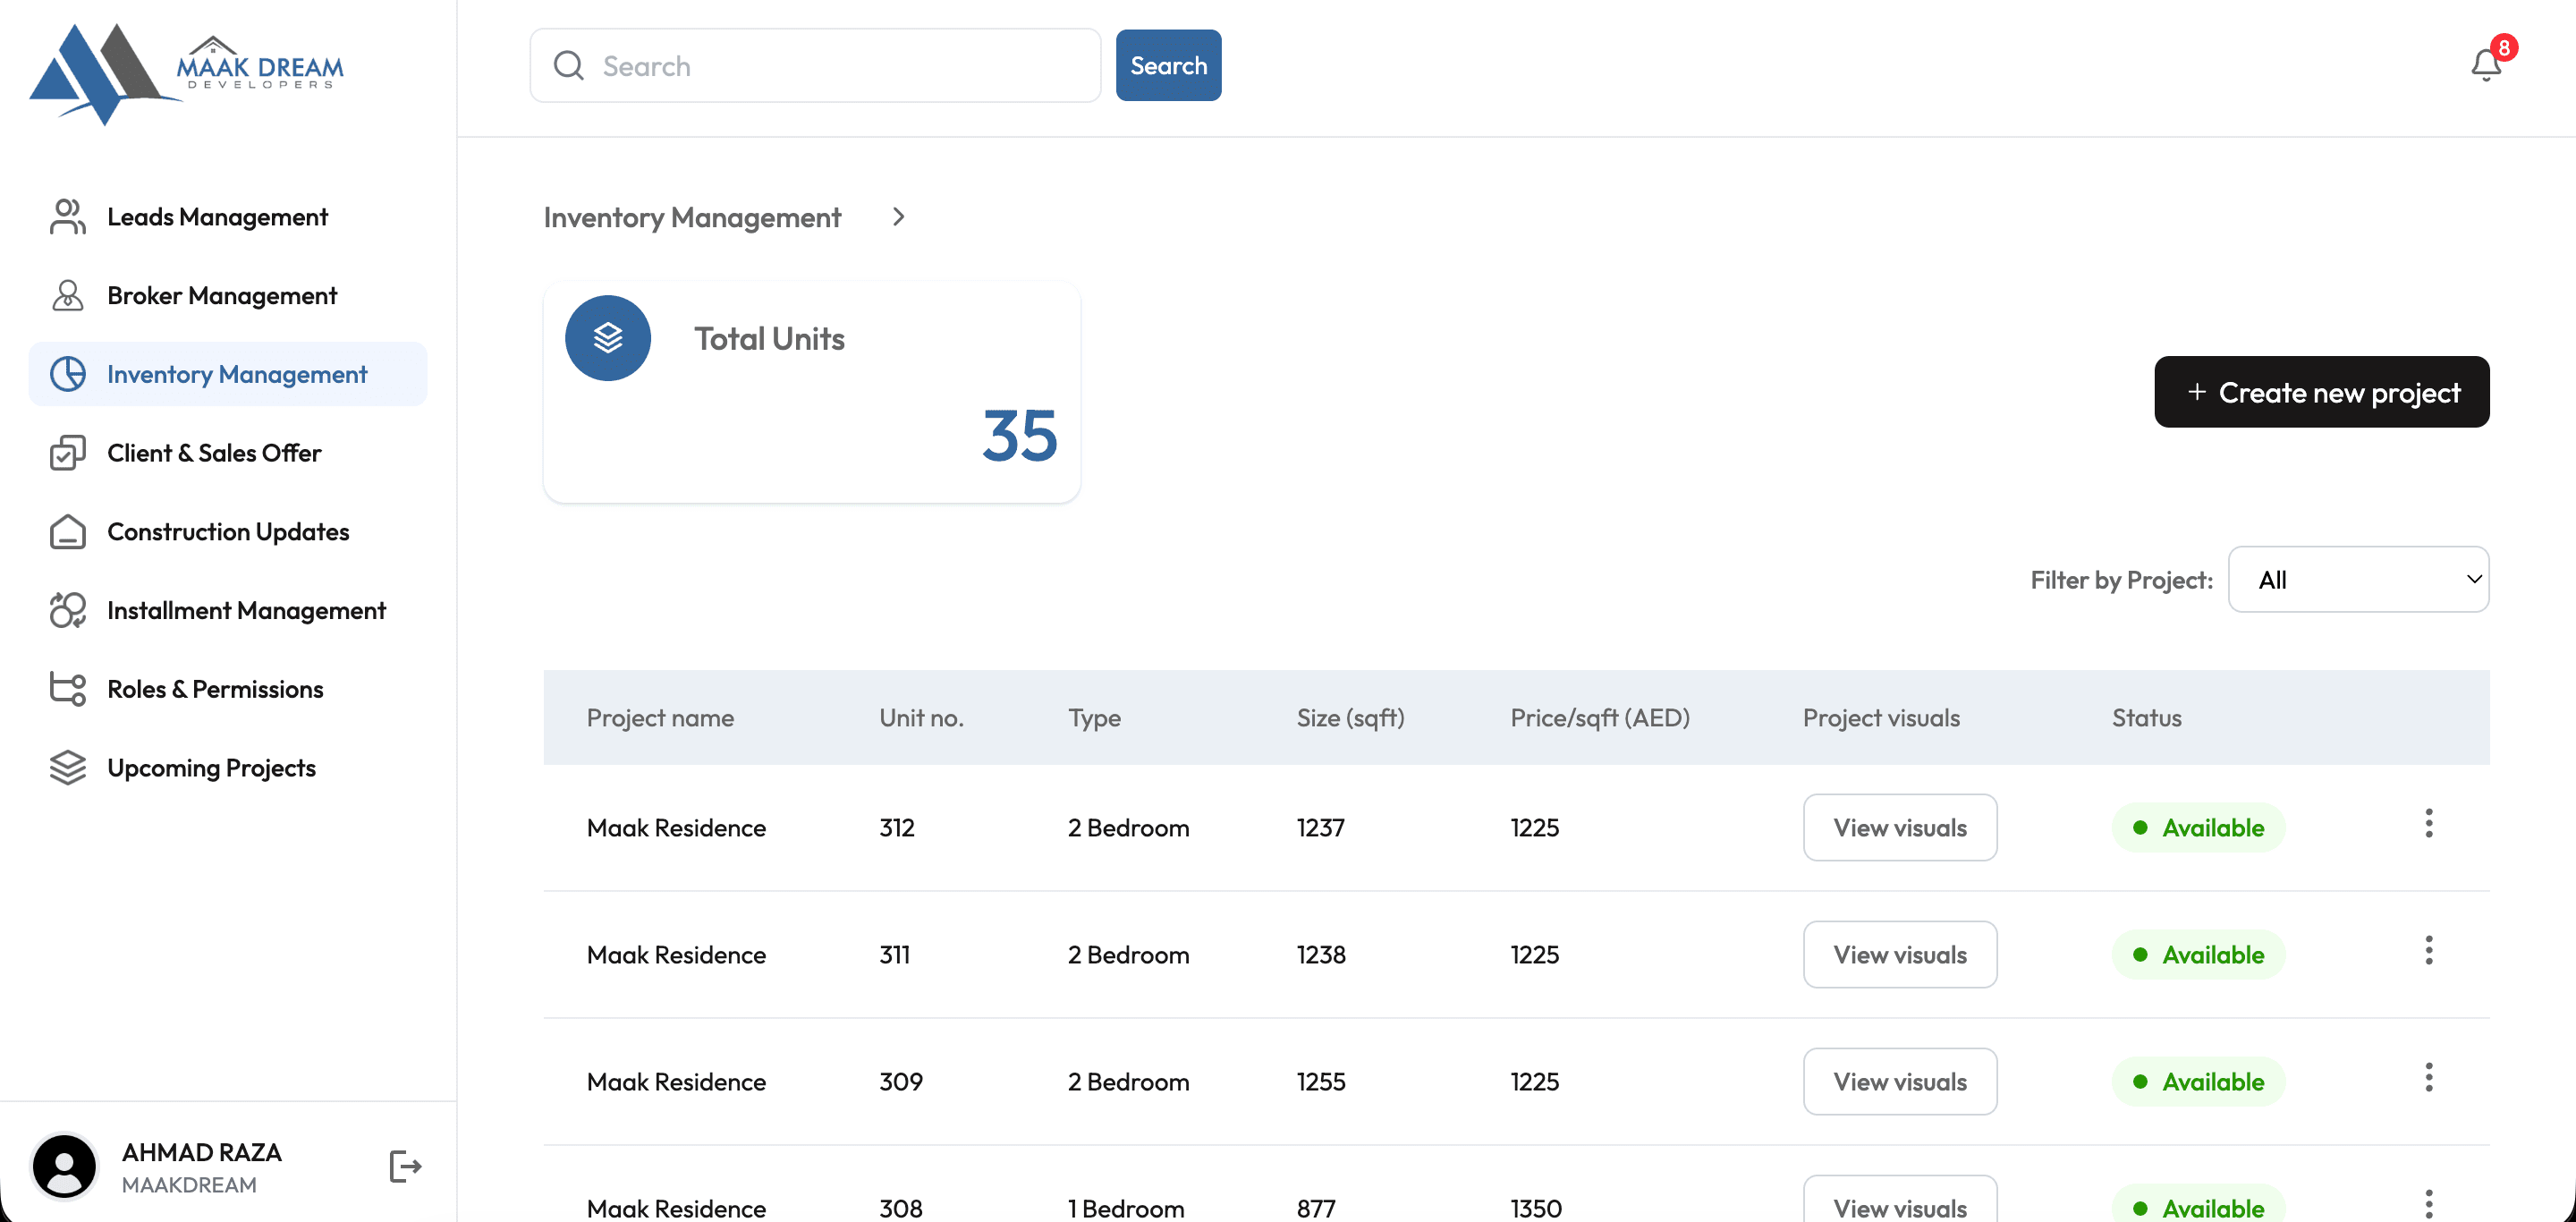 Real Estate & Construction · United Arab EmiratesMaak Dream Developers runs sales, inventory and delivery on one governed platformMaak Dream DevelopersRead the story
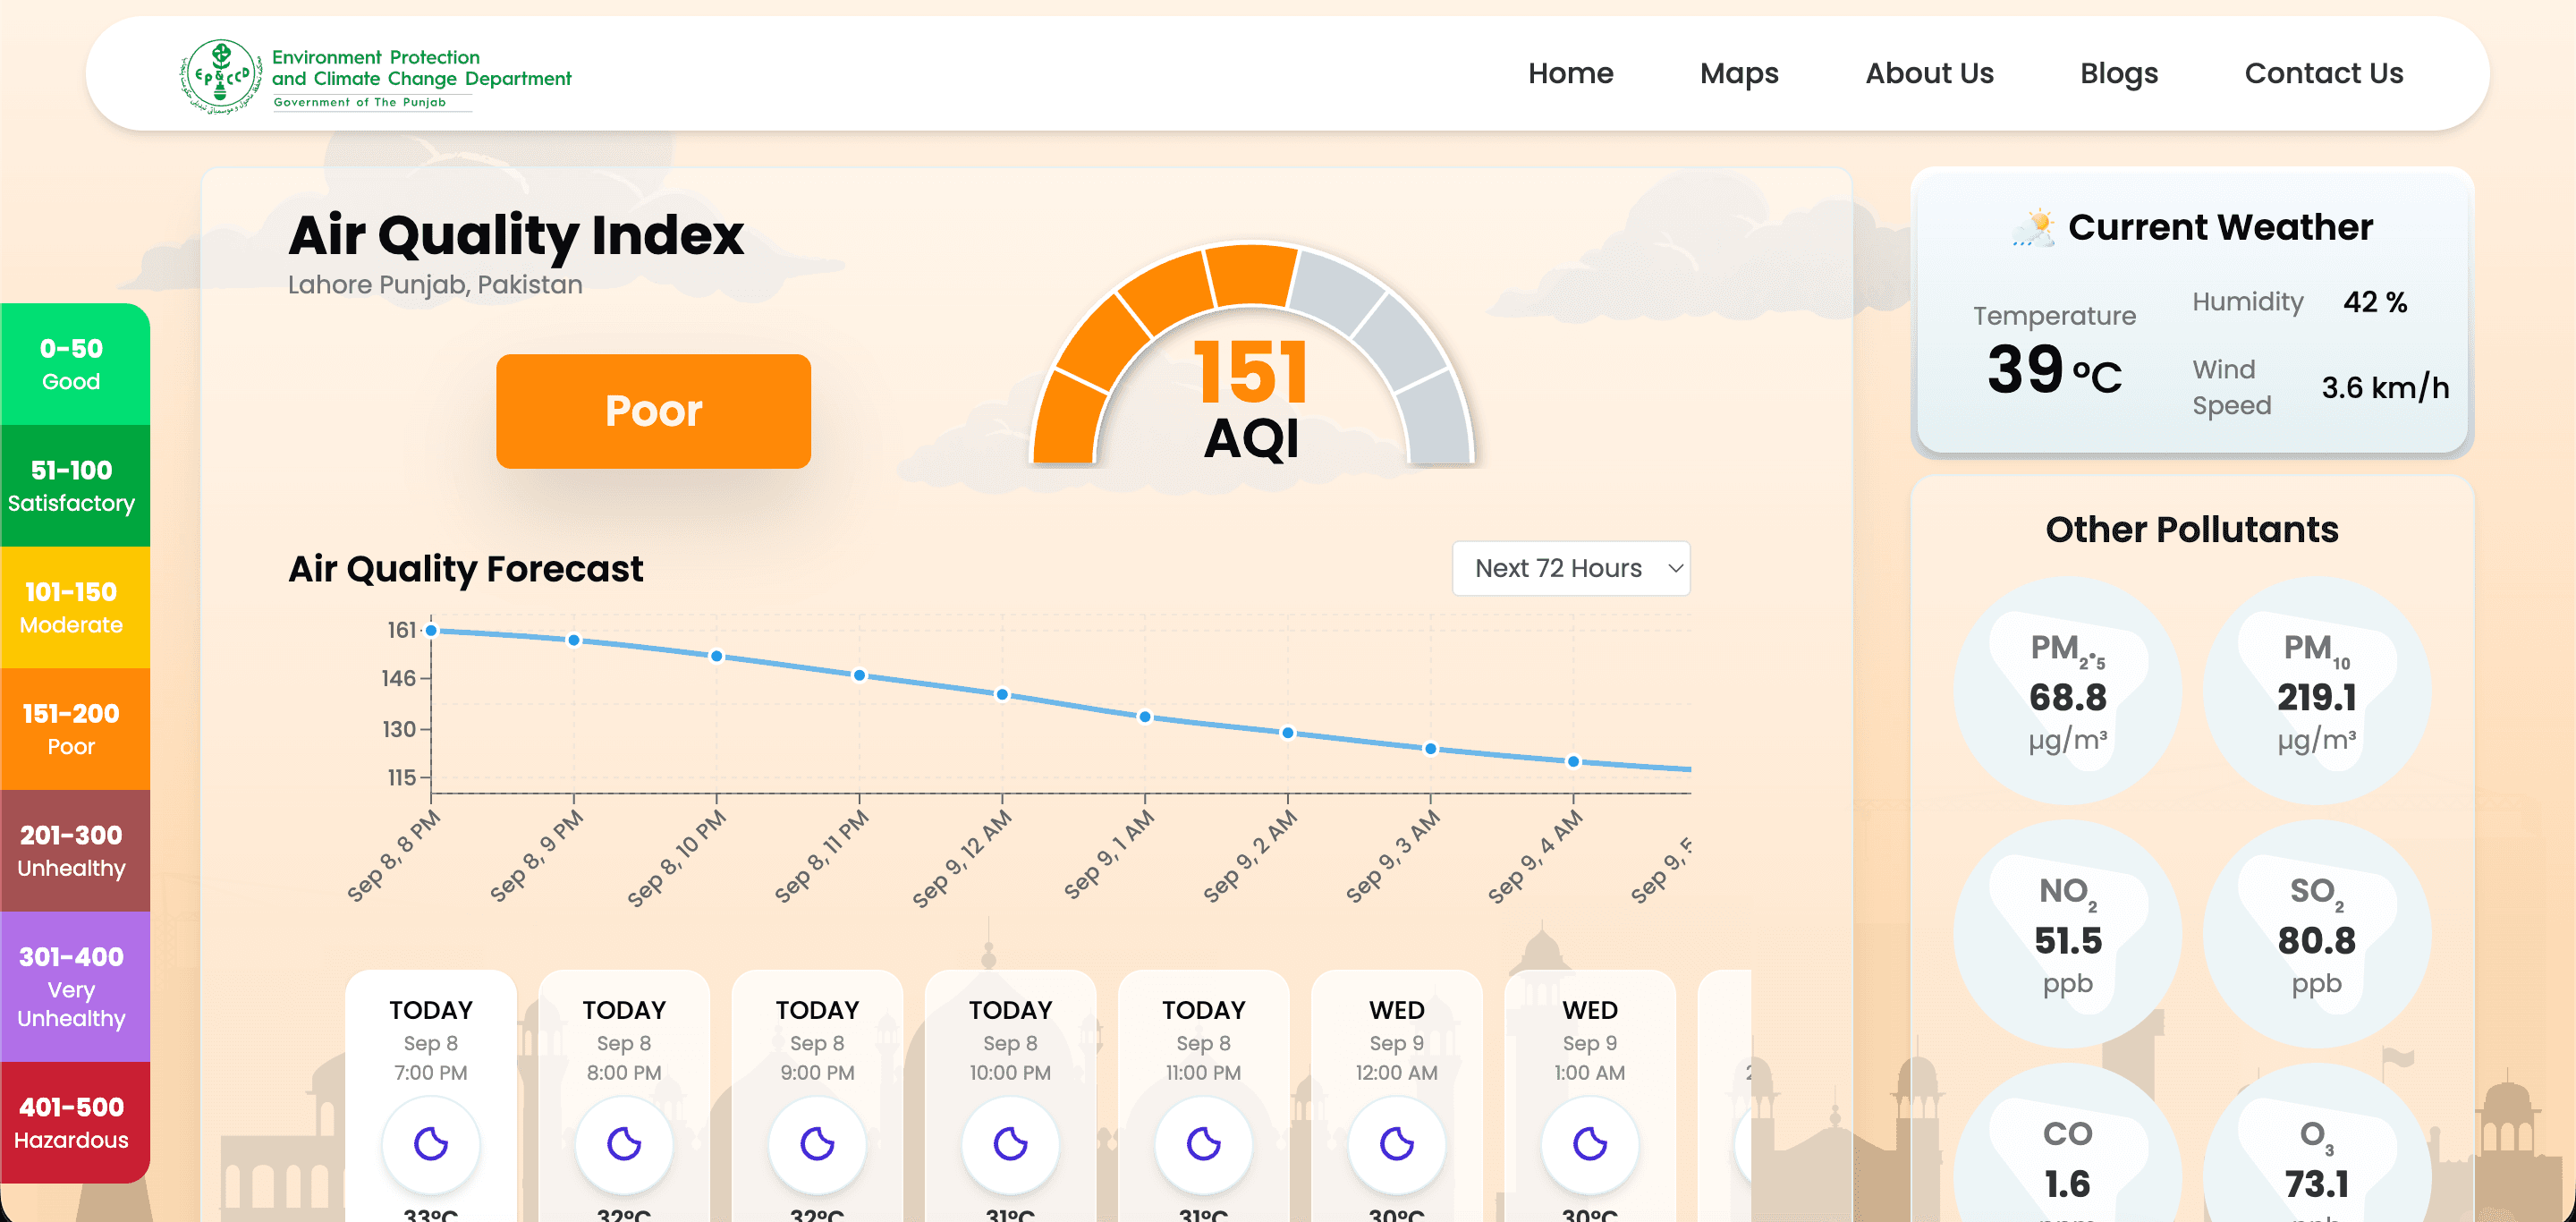 Public tenderPublic Sector & Government · PakistanPunjab's environment department gives citizens live, forecast-led air-quality intelligenceEPCCD, Government of the PunjabRead the story
 Manufacturing & Industrial · PakistanSiddique Sons Engineering moves HR and payroll onto a single system of recordSiddique Sons Engineering (Pvt) LtdRead the story
FAQ
Frequently asked questions
Can't find what you need? Ask us in the discovery session.
Free discovery session
Start your Generative AI & LLM Engineering project
Tell us what you're building. You'll hear back from an engineer, not an inbox.
- 1We reply within one business day to set up a 30-minute call.
- 2A senior engineer — not a salesperson — walks through your problem.
- 3You get a scoped proposal with timeline and cost. No obligation.
New projects & sales
[email protected]Existing clients & support
[email protected]